AI Analyst · GenAI · Agentic AI

Building AI that works in the real world.

I'm Sanjana Manimaran, an AI professional focused on turning complex business workflows into practical solutions with LLMs, retrieval-augmented generation, and AI agents.

⌖ Abu Dhabi, UAE✉ sanjanamaran30@gmail.com
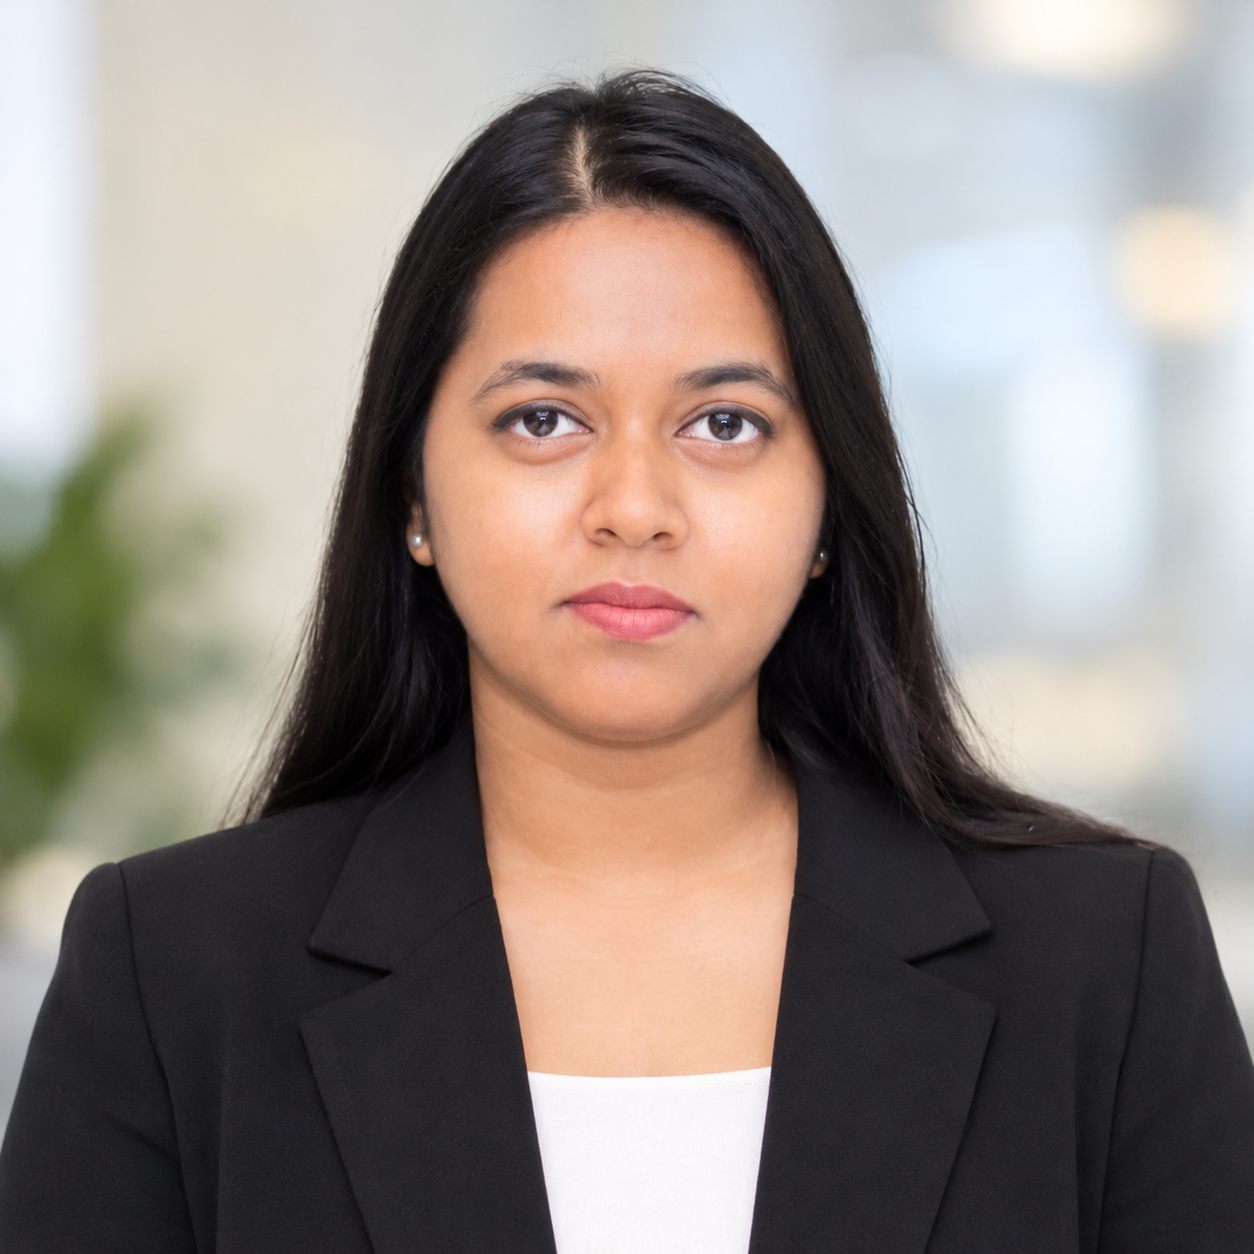
Professional portrait of Sanjana Manimaran
Sanjana ManimaranAI Analyst · GenAI Developer
A little about me

Curiosity, engineering
and useful AI.

I enjoy working at the intersection of language models, software engineering, and real business needs.

My approach

Build thoughtfully. Ground outputs in context. Make workflows more useful.

From proof of concept to workflow automation

My experience includes building AI-powered document workflows, semantic search systems, and agentic pipelines for enterprise use cases. I have worked with GPT, Claude, and other LLM-based approaches, connecting models to relevant data and tools through APIs and retrieval pipelines.

I care about practical outcomes: helping teams find information faster, reducing repetitive document work, and creating systems that are easier to review and use.

Generative AIRAG pipelinesAgent orchestrationDocument automationSemantic search
Selected work

Projects with purpose.

AI workflows designed to reduce manual effort, connect knowledge, and support better decisions.

PROJECT 01 · KNOWLEDGE SYSTEMS⌘

Zeb Wiki

An agent-based knowledge workflow that turns scattered project documents into a structured, searchable wiki, inspired by Andrej Karpathy’s “LLM Wiki” concept.

LangChain OrchestratorAgentCoreClaude Sonnet 4.5PostgreSQLAWS S3Human-in-the-loop
↗ 90% less time locating past project documentation.
Explore problem, architecture & my role

01 · Problem

Project knowledge was spread across Teams and SharePoint documents. Finding scope, technologies, project context, or similar past work required manually reviewing multiple files, making knowledge reuse slow.

02 · Solution & architecture

Built an agent-based wiki pipeline inspired by Andrej Karpathy’s LLM Wiki idea: turn source documents into structured entities and persistent Markdown knowledge pages, then make them discoverable through semantic retrieval.

Teams / SharePoint docs→LangChain Orchestrator Agent→AgentCore Executor→Entity extraction→Similarity / duplicate check→Wiki read / write→S3 + PostgreSQL embeddings
  • Entity extraction: identify projects, clients, technology stacks, scope, and other attributes.
  • Wiki management: create or update Markdown pages and maintain the schema as new entity types appear.
  • Semantic retrieval: store wiki Markdown in AWS S3 and embeddings in PostgreSQL for similar-project discovery.
  • Human-in-the-loop: include a human review checkpoint for ambiguous or low-confidence extracted details and proposed knowledge updates before they are accepted.

Reference: Inspired by Andrej Karpathy’s “LLM Wiki” concept, which treats a knowledge base as a maintained, evolving collection of linked notes rather than a one-off document summary.

03 · My role

  • Designed and implemented the agentic workflow for transforming source documents into structured wiki knowledge.
  • Built the LangChain orchestration flow and connected document processing, entity extraction, similarity detection, and wiki management tools.
  • Implemented S3 storage for Markdown pages and PostgreSQL embeddings for semantic search.
  • Worked on dynamic entity/schema management and integrated Claude Sonnet 4.5 for document understanding and extraction.
  • Evaluated extraction quality and identified agent execution cost as an optimization area.

04 · Results

Created a searchable organizational knowledge base, enabled discovery of similar projects, and reduced time spent locating previous project documentation by 90%. The work also identified cost-efficiency opportunities for production-scale use.

05 · Tech stack

Python · LangChain · AgentCore · Claude Sonnet 4.5 · AWS S3 · PostgreSQL · Embeddings · RAG / vector search · Markdown

PROJECT 02 · LEGAL AI§

NFI Redlining

RAG-based contract review proof of concept that compares vendor/customer contract clauses against company policies and suggests corrections in Microsoft Word.

PythonGPTRAGLangChainPostgreSQLFastAPI
↗ Made policy discrepancies easier to identify and review in-document.
Explore problem, architecture & my role

01 · Problem

Legal teams needed a more efficient way to identify discrepancies between vendor/customer contracts and internal company policies.

02 · Solution & architecture

Processed documents submitted through a chatbot/API, chunked the contract text, retrieved relevant policy passages from PostgreSQL using semantic similarity, and sent the contract chunks plus retrieved context to GPT for analysis.

Document via chatbot / API→Ingestion & chunking→PostgreSQL policy search→RAG context + GPT→Word Track Changes & comments

Potential discrepancies were shown directly in the Word document by striking through flagged text and adding suggested corrections as comments for legal review.

03 · My role

  • Developed the document-processing workflow, chunking, similarity search, and LLM analysis.
  • Implemented the RAG pipeline over company policy content stored in PostgreSQL.
  • Integrated GPT-based clause comparison and Microsoft Word Track Changes/comment automation.
  • Helped connect the workflow to chatbot/API-based document submission.

04 · Results

Delivered a working POC that helped surface policy deviations faster and placed proposed corrections in the document for legal teams to review, reducing manual review effort.

05 · Tech stack

Python · GPT · RAG · LangChain · PostgreSQL / vector search · FastAPI / REST API · NLP · Microsoft Word automation

PROJECT 03 · WORKFLOW AUTOMATION↗

Apollo — SOW & LOE Automation

AI-assisted drafting workflow for Statements of Work and Levels of Effort, connecting GPT with organizational context and document-generation tools.

GPTRAGPython APIsJinja2Word & Excel
↗ 1–2 days to about 1 hour for drafting.
Explore problem, architecture & my role

01 · Problem

Sales executives and technical leads manually prepared SOW and LOE documents for customer engagements. This involved gathering requirements, scope, effort, and cost details and repeatedly formatting content.

02 · Solution & architecture

Connected GPT to API tools that retrieve relevant project/customer context through RAG, store generated content in Excel, and populate standardized Word templates dynamically with Jinja2.

User instructions→GPT→RAG retrieval tool→Context-aware SOW / LOE→Excel + Jinja2 Word templates

Human review remains important before generated commercial or scope documents are finalized.

03 · My role

  • Developed/implemented API-based tools for RAG retrieval, Excel content storage, and Word template population.
  • Integrated GPT with backend tools so retrieved information could ground generated drafts.
  • Worked on Jinja2 template binding and the structured document-generation workflow.

04 · Results

Reduced drafting and formatting time from approximately 1–2 days to about one hour, an estimated 85% reduction in manual effort. Standardized output and reduced repetitive copy-paste work.

05 · Tech stack

GPT · RAG · Python · REST APIs · Database retrieval · Jinja2 · Microsoft Word · Microsoft Excel

PROJECT 04 · GENAI POC⤴

Precisely Template Migration

Explored LLM-assisted conversion of OpenText Exstream XML templates to Precisely RapidCX, evaluating output accuracy and functional/visual fidelity.

GenAIClaudeAmazon Nova ProXMLAWS
↗ POC targeted 85% automated conversion coverage with minimal manual adjustments.
Explore problem, architecture & my role

01 · Problem

Moving legacy OpenText Exstream templates to Precisely RapidCX can be complex and manual, particularly when templates vary in structure and complexity.

02 · Solution & architecture

Parsed and analyzed source XML, identified reusable patterns, and used prompt-engineered LLM workflows to generate corresponding target structures. Tested across template complexity levels and compared outputs against originals.

Exstream XML→Parse & inspect structure→Prompt / LLM conversion→RapidCX target structure→Accuracy & fidelity evaluation

03 · My role

  • Analyzed template structure and identified reusable conversion patterns.
  • Designed and refined prompts based on conversion test results.
  • Compared Claude and Amazon Nova Pro outputs.
  • Evaluated accuracy, visual fidelity, functional equivalence, and limitations across complexity levels.

04 · Results

Demonstrated technical feasibility, documented conversion patterns and failure cases, and established evaluation considerations. The POC targeted 85% conversion coverage with minimal manual adjustments; this is a target, not a claimed measured result.

05 · Tech stack

Generative AI / LLMs · Prompt engineering · XML parsing · Claude · Amazon Nova Pro · AWS · RAG / document knowledge base

Project details are summarized at a high level; client-confidential implementation details are intentionally omitted.

Technical toolkit

Tools I build with.

A practical stack across language models, retrieval, agentic workflows, APIs, data stores, and cloud platforms.

✳

LLMs & Generative AI

GPT, Claude, Gemini, prompt engineering, model evaluation, output grounding, cost and latency considerations.

⌘

RAG & AI Agents

Retrieval-augmented generation, LangChain, LangGraph, Strands Agents, AgentCore, orchestration, tool calling.

⌁

Programming & APIs

Python, SQL, FastAPI, REST APIs, workflow automation, API integrations, data pipelines.

▤

Data & Vector Search

PostgreSQL, vector search, embeddings, DocumentDB, Databricks, semantic similarity retrieval.

☁

Cloud & DevOps

AWS, Microsoft Azure, Docker, Azure Pipelines, CI/CD, Git, S3-based knowledge storage.

▧

Workflow Engineering

Jinja2 templates, document generation, Microsoft Word automation, Excel integration, orchestration.

Experience & learning

Where I've been building.

Zeb/Avasoft · AI Analyst

October 2024 – August 2026

Designed, built and deployed enterprise Generative AI, LLM, RAG and Agentic AI solutions for document automation, knowledge management and contract analysis.

Roles & Responsibilities

  • Built RAG pipelines covering document ingestion, chunking, embeddings, vector search and retrieval
  • Designed agentic AI workflows with tool calling and multi-step reasoning
  • Developed REST APIs with FastAPI and integrated LLMs with databases and business tools
  • Implemented tool calling, prompt engineering and multi-step agent workflows
  • Evaluated accuracy and optimized cost and latency of AI workflows
  • Containerized applications with Docker and deployed through CI/CD pipelines on AWS and Azure
  • Worked with business and technical teams to turn requirements into AI solutions

Education

M.Tech — Integrated Software Engineering
Vellore Institute of Technology · 2019–2024
CGPA: 7.79 / 10

Certifications

✦Databricks Certified Machine Learning Professional
✦Microsoft Azure Fundamentals (AZ-900)
✦Introduction to Software Engineering — IBM
Let's connect

Have an interesting AI problem to solve?

I'm open to opportunities across AI engineering, Generative AI, LLM applications, and agentic systems. Let's connect.

Email me

sanjanamaran30@gmail.com

Write in Gmail

Call me

PHONE_NUMBER